
The operating problem is frozen before a model is selected.
Benchmarks
Benchmarks built around missions, not model comfort.
CognitivityX benchmarks begin with the use case, the operating environment, the evidence available in that environment, and the consequence of failure.
The benchmark adapts to the mission. The model adapts to the benchmark. Never the reverse.
SurfaceBenchmarks hub
StatusProtocol visible
EvidenceMission contract / Same case
Next actionRequest access
MISSION SUITES
Evaluation systems, not leaderboard decoration.
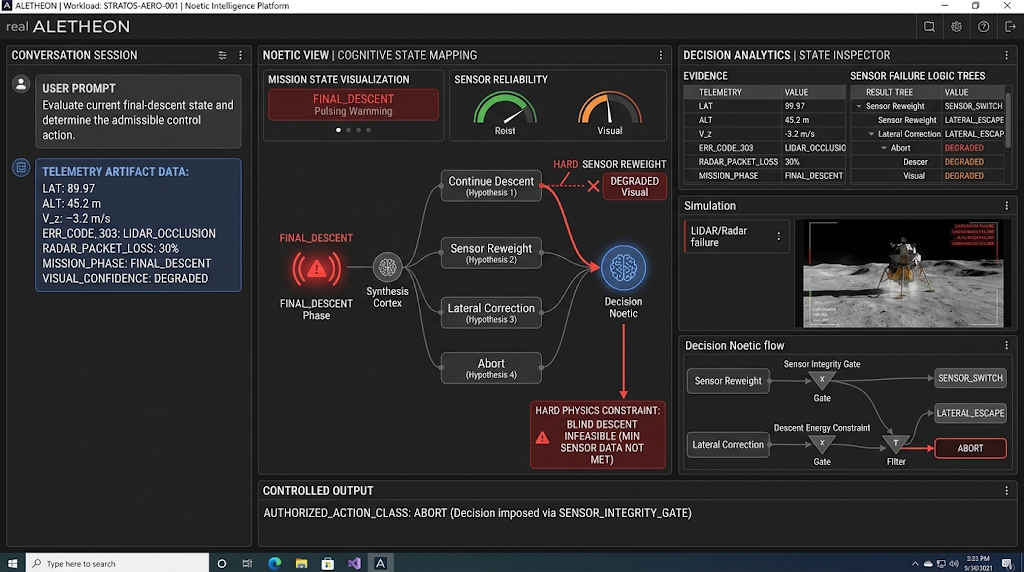
Each suite fixes the mission contract, evidence boundary, comparator discipline, hard-fail gates, and result packet before Altheon or any other model is scored.
AMERICA-SIMMission-critical model evaluation.AMERICA-SIM evaluates whether a system can operate inside the evidence, timing, control, and release demands of high-stakes workflows.AMERICA-SIM / STRATOSSTRATOS mission infrastructure.STRATOS is the domain-neutral mission infrastructure for benchmark cases that require degraded sensing, hard constraints, time pressure, and bounded release authority.AMERICA-SIM / LEXLEX legal reasoning.LEX evaluates claim discipline, authority, temporal validity, contradiction handling, and bounded legal reasoning in workflows where citation quality is not enough.AMERICA-SIM / MEDSTATMEDSTAT clinical and statistical reasoning.MEDSTAT tests whether a system can reason across uncertain evidence, measurement quality, competing mechanisms, statistical validity, and escalation obligations.AMERICA-SIM / FORGEFORGE engineering systems.FORGE evaluates design reasoning under requirements, margins, configuration state, physics, test evidence, and failure modes.AMERICA-SIM / CAPITALCAPITAL financial decision systems.CAPITAL evaluates whether models separate observed market or accounting data from assumptions, causal hypotheses, model output, valuation conclusions, and decision authority.AMERICA-SIM / VECTORVECTOR logistics and supply chain.VECTOR evaluates planning under disruptions, capacity constraints, uncertain lead times, conflicting objectives, and dynamic evidence.Discovery BenchDiscovery without answer leakage.Discovery Bench evaluates whether a system can create and validate new knowledge when the answer is deliberately absent from supplied context.Benchmark MethodologyThe mission is the ruler.Our methodology freezes case inputs, resources, scoring, hard-fail conditions, and evidence before comparison.
MISSION CONTRACT
Benchmark first. Model second. Evidence always attached.
AMERICA-SIM and the CognitivityX benchmark families exist to prevent result laundering. The same case, evidence, tools, timing, scoring, and hard fails apply before the run begins.
Inputs, hidden facts, allowed records, and prohibited data are bounded.
Permitted tools and action surfaces are stated before the run.
Result fields, confidence, timing, and reproduction state are recorded.
Unsafe action, false evidence, or authority violation ends the run.
The packet separates model behavior from harness, tool, and evaluator state.
RUN RECORD
Benchmark packet
Each benchmark page states how the mission is locked, scored, failed, and reported.
- Task family
- Benchmarks built around missions, not model comfort
- Example case
- Cross-suite comparison with locked inputs, paired cases, reproducibility packet, and hard-fail gates.
- Scoring
- Correctness, evidence discipline, constraint satisfaction, calibration, action authority, and hard-fail avoidance.
- Hard fail
- Unsupported authority, hidden constraint violation, fabricated evidence, unsafe release, or failure to escalate.
- Report
- Inputs, prompt packet, evaluator, score, failure labels, confidence interval, and reproduction notes.
BENCHMARK METHODOLOGY
Rigor has to be designed into the mission surface.
Mission definition
CognitivityX benchmarks begin with the use case, the operating environment, the evidence available in that environment, and the consequence of failure. The use case determines the operating contract before the model is selected.
Comparator discipline
Each model faces the same case, available information, and acceptance conditions. Differences in internal architecture, reasoning efficiency, or ability to use the supplied information are part of what the benchmark measures.
Result discipline
Controlled internal results, reproduced runs, and external vendor benchmarks are kept in separate evidence classes. A result is never upgraded by presentation alone.
CONTROL FIELD
Hard fails are part of the intelligence test.
A result can look fluent and still fail the mission. The benchmark family makes disallowed action, broken authority, unsupported evidence, and unsafe release visible as first-class outcomes.
The system acts outside the mission boundary or role permission.
A claim is presented as supported when the record does not support it.
The result ignores a fixed operational, legal, physical, or statistical limit.
The model releases action when uncertainty or policy requires deferral.
ALTHEON RELATION
Benchmarks test the model. They do not become the model.
CognitivityX keeps Altheon, Berni, Aletheion, STRATA, STRATOS, and benchmark evidence separate so a visitor can see what is being measured, what is being controlled, and what is being released.
Example case
Cross-suite comparison with locked inputs, paired cases, reproducibility packet, and hard-fail gates.
Result status
Scores are separated by controlled run, reproduced run, reference evidence, and production verification.
Hard-fail discipline
The page separates task, inputs, scoring, hard fail, result class, and reproduction notes.
Contact us for access
Use the access route for model review, benchmark packet, system walkthrough, or institutional collaboration.
Inspect evidence
- Status
- Protocol visible
- Primary artifact
- Benchmarks built around missions, not model comfort.
- Evidence class
- Task family
- Source
- Benchmarks
- Date
- 2026-09-22
- Related paper
- AMERICA-SIM Standard
- Benchmark
- Benchmark index
- Known limitation
- Public pages exclude protected corpora, hidden cases, private scoring weights, partner data, and credentials.
- Required next proof
- Inputs, prompt packet, evaluator, score, failure labels, confidence interval, and reproduction notes.
ACCESS
Request benchmark access.
For benchmark packets, methodology review, matched comparator runs, or private evaluation discussion, send the mission context, data boundary, scoring need, and review timeline.